
Start your first crawl
Choose a URL, run a small audit and find the results.
On this page
Before you start
A crawl explores a site from a starting URL and analyses the pages it discovers. You do not need to connect Google Analytics or Search Console first. Use a site you are authorised to audit and check your account’s audit allowance.
Already have an audit? Read Understanding crawl results.
1. Choose the site and engine
Open Crawl and enter the complete site address, such as https://example.com/. Start from its final address: if the non-www version redirects to www, use the latter.
Choose the engine offered by the launcher. Classic is the historical engine; Spider · beta, when available, supports progress monitoring, pausing and adjusting exploration rules. Settings and capabilities can differ between engines.
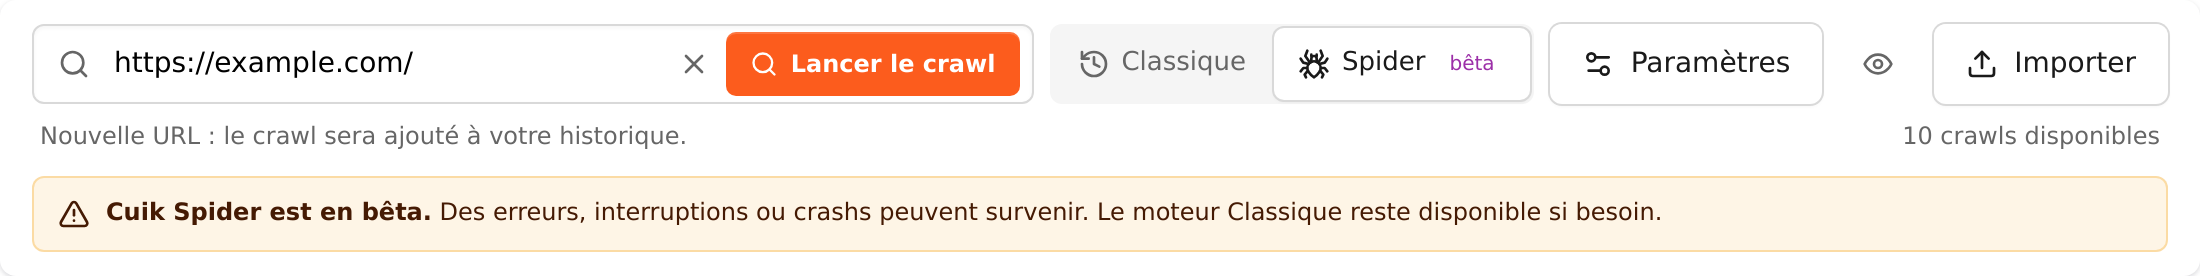 Spider and its settings. Available features depend on the engine and your plan.
2. Start with a small scope
For an initial test on a small business site, open Settings, set a limit of 1,000 URLs, choose 2 URLs/s and leave JavaScript rendering off. These are suggested starting values, not product defaults. Checked resources and links may also count towards the URL limit.
Keep robots.txt rules enabled. With Spider, use the scope path to restrict exploration to a section. Enable JavaScript rendering only when the initial HTML lacks the content or links you need.
Review the Active configuration summary. For large sites, shops or protected sites, read the advanced guide before expanding the audit.
3. Choose documents and launch
If you want a Google Sheet or Slides presentation, choose templates available to your account in the settings. Check both selections if you want both documents. Document generation happens separately from page collection.
Click Start crawl. This uses your audit allowance. Avoid clicking repeatedly or starting a new crawl just because results take time to appear; look for the existing crawl in the list first.
4. Find the results
Open the crawl from the list to follow its status. Finalisation can continue after URL collection. When results become available, begin with the overview, then inspect issues and the affected URLs.
Documents may become available later. If you did not request them initially, use Generate documents to choose templates and prepare them from the existing audit.
If the audit stops or expected pages are missing, note the message and crawl ID. The troubleshooting guide explains what to check before starting again.